Ask AI
Ask AI is an AI-powered assistant built into every workspace that analyzes your security data and provides actionable insights through natural language conversation. Rather than manually sifting through assets, vulnerabilities, and notes, you can ask the assistant questions and receive contextual answers drawn directly from your workspace data.
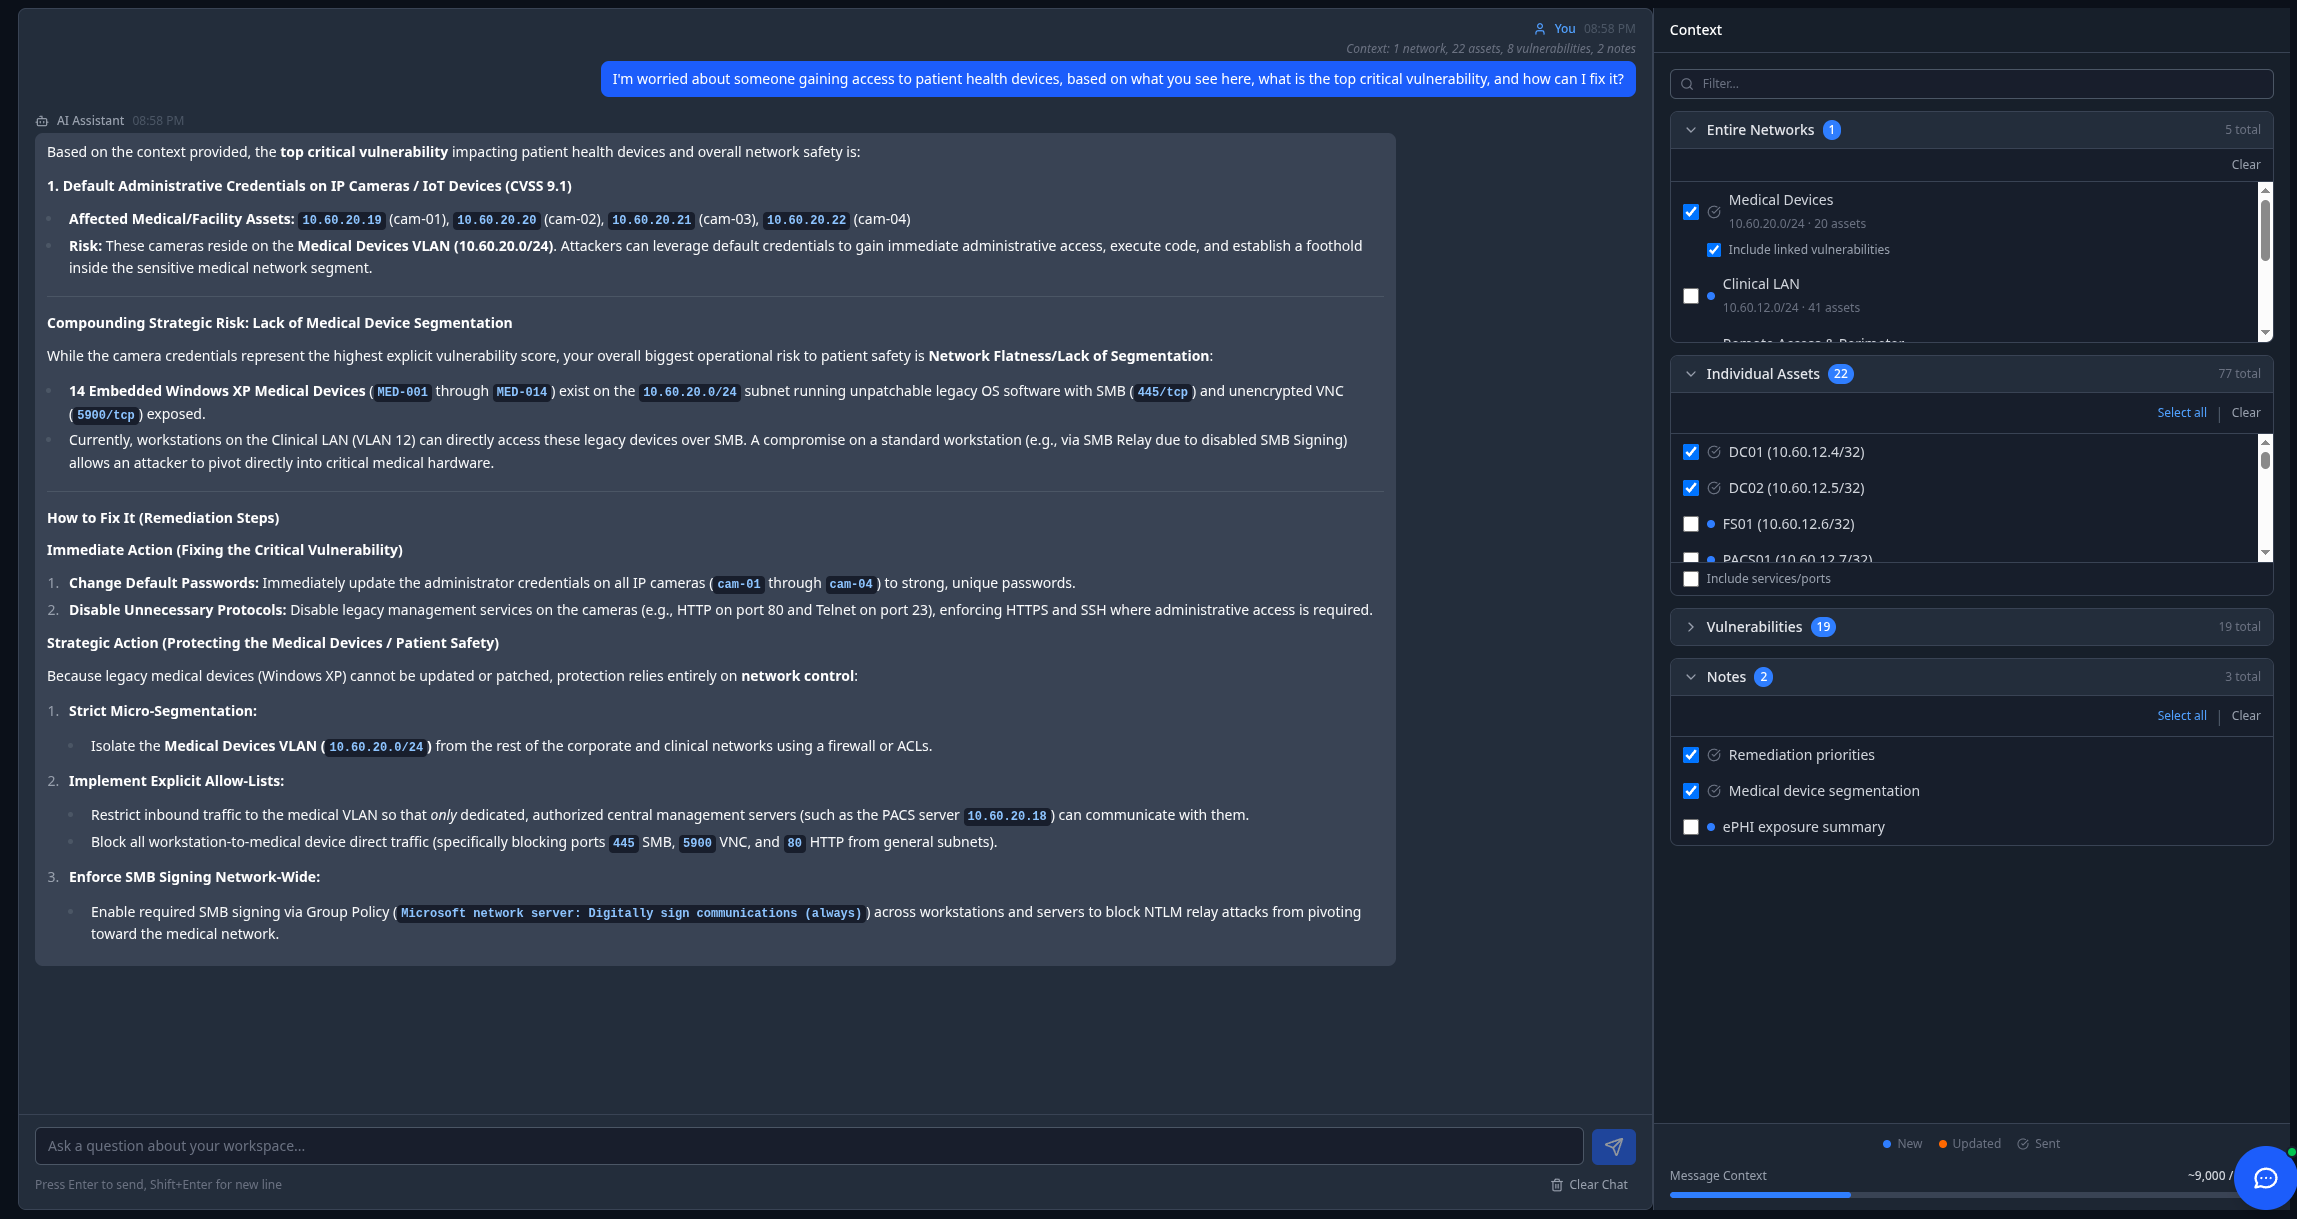
Ask AI is available to Premium and Self-Hosted users. Free-tier users do not have access to this feature. Self-hosted deployments configured with a local Llama router have unlimited usage.
How It Works
Ask AI operates as a per-user, per-workspace conversation. Each user in a workspace has their own private conversation thread with the assistant. When you send a message, Hawkra gathers the workspace data you have selected as context, combines it with your question, and sends it to the configured AI backend. The assistant then returns a response informed by your actual security data.
The assistant can use Anthropic, DeepSeek, Gemini, OpenAI (self-hosted only), or a local Llama router. Your administrator chooses the provider, and can also choose the model and, for models that support reasoning, the thinking level. Changes take effect immediately, without a restart.
- Anthropic, DeepSeek, or Gemini: Your selected context and question are sent to the chosen provider's API. This requires a configured API key and, on SaaS deployments, is subject to monthly message quotas.
- OpenAI (self-hosted only): Your administrator links a ChatGPT account (no API key), and requests are sent to OpenAI using that account's ChatGPT plan.
- Llama router: Available for self-hosted deployments. Your data stays on your infrastructure and is processed by a locally hosted model behind llama-swap or another OpenAI-compatible router. There are no message quotas since you own the hardware.
Context Selection
Before sending a message, you can select which workspace data to include as context for the AI. This gives you precise control over what information the assistant can see and reason about.
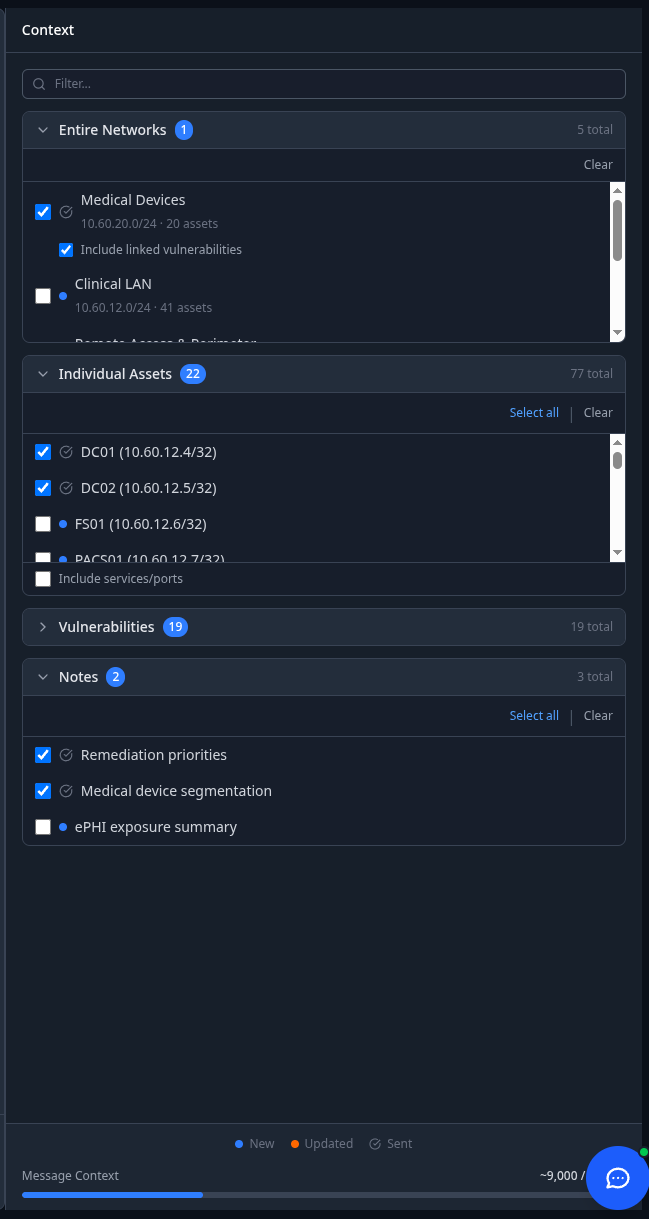
Available Context Types
| Context Type | Description |
|---|---|
| Assets | Individual assets with IP addresses, hostnames, OS details, and optionally their discovered ports/services |
| Networks | Entire networks including all their assets, ports, and optionally linked vulnerabilities |
| Vulnerabilities | Specific vulnerabilities with severity, CVSS scores, CVE/CWE references, and optionally their affected assets |
| Notes | Your encrypted workspace notes (decrypted for context, then re-encrypted at rest) |
Context Toggles
When selecting context, you have additional toggles to control the level of detail:
- Include services/ports: When enabled for asset selections, port and service enumeration data is included alongside each asset. This is always enabled for network-based selections.
- Include affected assets: When enabled for vulnerability selections, the affected assets and ports are included with each vulnerability. This is always included for network-based selections when vulnerabilities are toggled on.
Example Questions
- "What are the most critical vulnerabilities in the 10.0.1.0/24 network and which assets are affected?"
- "Based on the open ports on this server, what attack vectors should I prioritize?"
- "Summarize the security posture of the assets I've selected."
- "Are there any common weaknesses across these vulnerabilities that suggest a systemic issue?"
- "What remediation steps would you recommend for the vulnerabilities on this web server?"
Token Usage and Quotas
On SaaS deployments, Ask AI usage is tracked on a monthly per-user basis.
| Tier | Monthly Message Limit |
|---|---|
| Free | Not available |
| Premium | 100 messages per month |
| Self-Hosted (Cloud provider) | Unlimited (configurable) |
| Self-Hosted (Llama router) | Unlimited (no tracking) |
Your current usage is displayed in the AI interface. When you approach or reach your monthly limit, you will see a notification. Quotas reset at the start of each calendar month.
Self-hosted deployments using a Llama router bypass all quota checks entirely. Since the model runs on your own infrastructure, there is no usage tracking or rate limiting.